Audio Modality

Curate Audio Data for Training AI & ML Models

Transcribe speech, diarize speakers, tag events and segment audios with AI engine to consolidate audio data at faster pace

Audio

One layer for every type of audio labelling

From word-level transcription to speaker diarization, the data labelling layer routes every clip to the right audio modelities, auto-labelling engines s provide results with confidence, while those above threeshold are passed automatically others are directly sent to a human reviewer so nothing gets shipped unverified.
Task Types

Complete Toolkit to Curate Audios

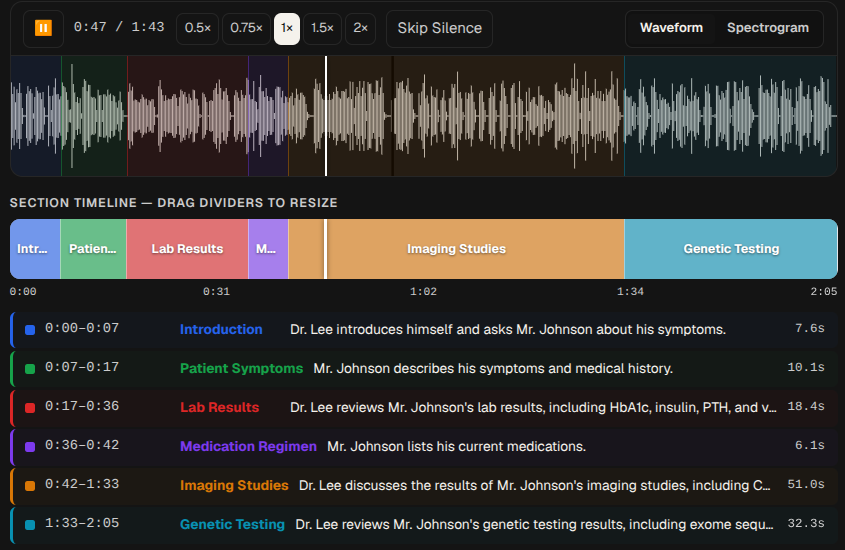
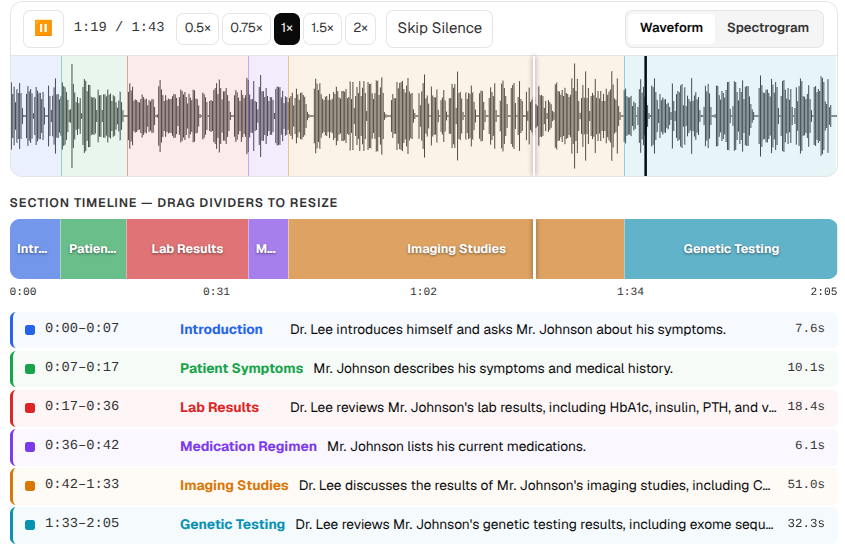
Audio segmentation — labeled temporal sections across a recording Audio Segmentation
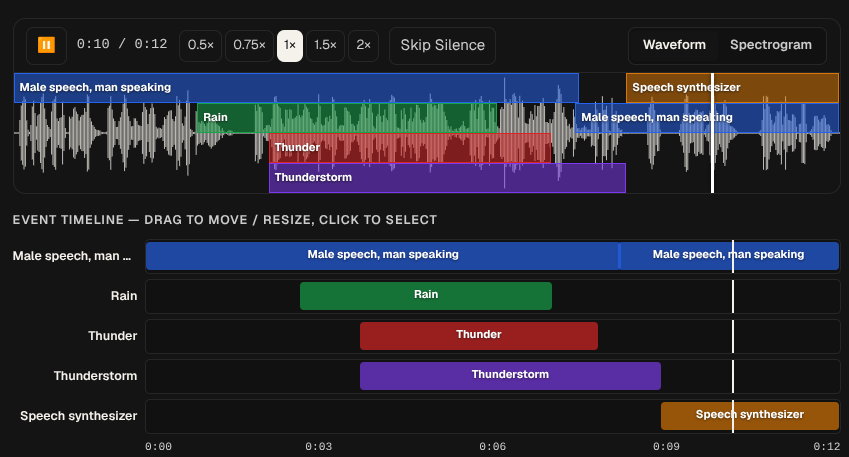
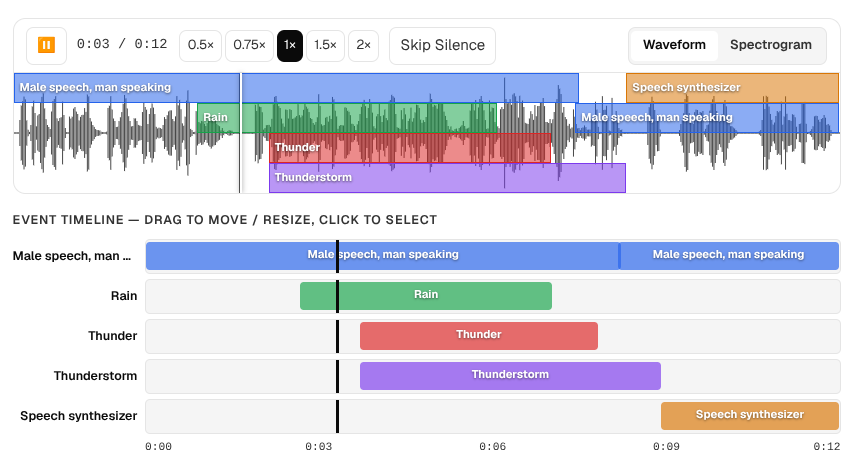
Sound event detection — polyphonic event timeline with detected events Sound Event Detection
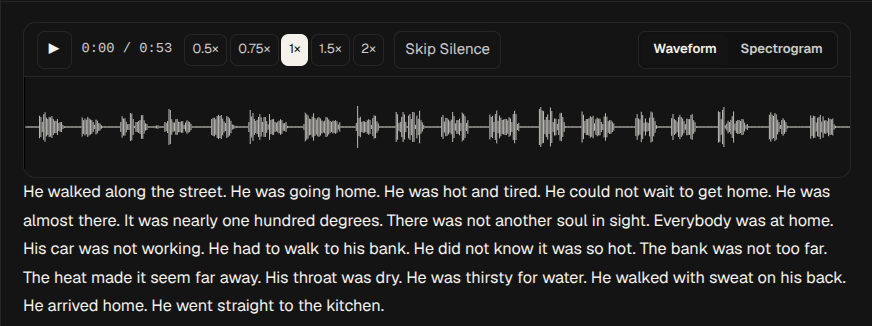
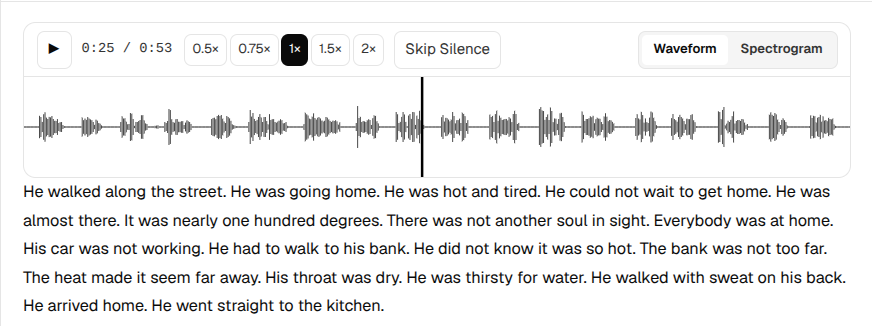
Transcription — AI-generated timestamped transcript with confidence score Transcription
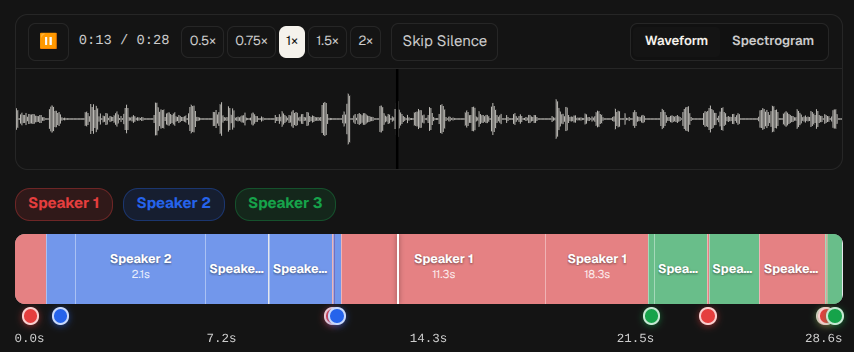
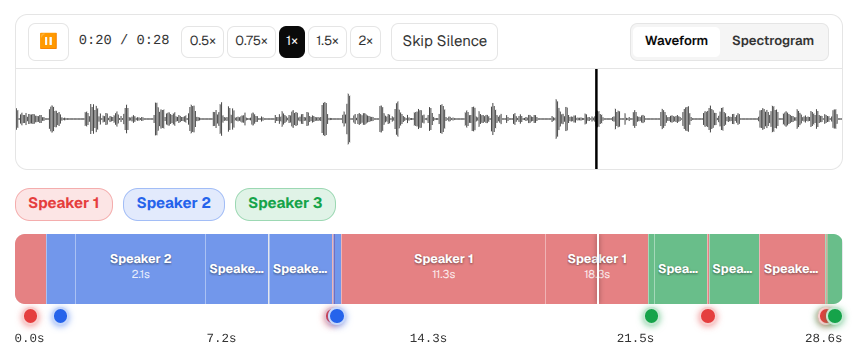
Speaker diarization — per-speaker timeline with transcript turns Speaker Diarization
Emotion detection — detected emotion, sentiment, and intensity with transcript Emotion Detection
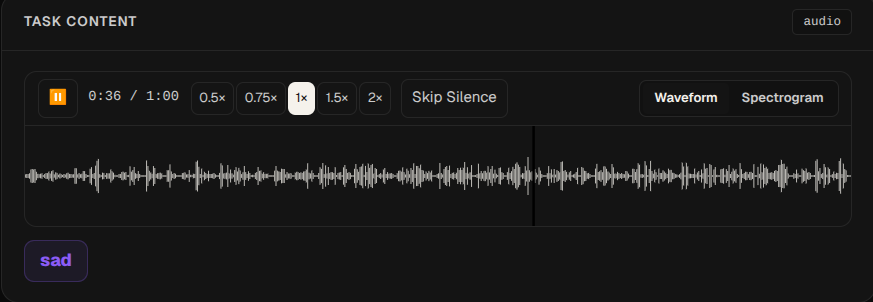
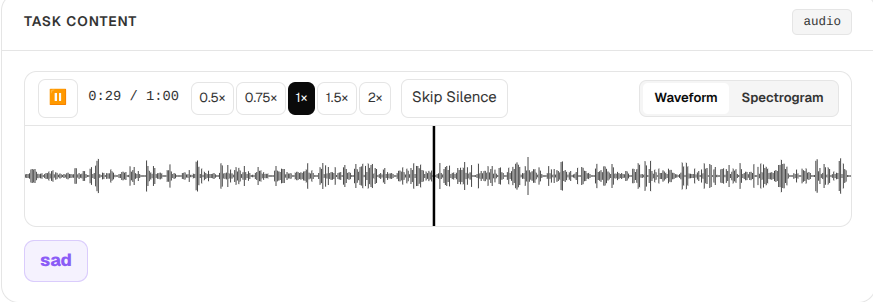
Audio classification — AI-assigned category label with confidence score Audio Classification
Built-In Automation

Everything you need to scale audio labeling

Ontologies
Customizable ontologies for every audio project

Build nested classification schemas specific to your domain, from simple tags to multi-level attribute hierarchies.

AI Assistance
Native AI integration with Whisper, AST & pyannote

Access AI engines integrated with Whisper for transcription, AST for segmentation and pyannote for speaker diarization natively faster, more accurate first-pass labels before any human intervention.

Analytics
In-depth performance analytics

Uncover insights on label quality and engine performance to optimize efficency, quality, and workforce efficiency.

Workflows
Configurable workflows for quality control

Guarantee quality throughout labeling pipelines with customizable review stages, consensus routing, and approval gates.

FAQ

Common questions

Transcription, audio classification, speaker diarization, emotion detection, sound event detection, and audio segmentation all routed through the same Label layer.

Every clip is transcribed and scored by the engine best suited to its task. Segments above the configured confidence threshold are accepted automatically everything else is queued for a review.

Yes. Ontologies are configured per project, from flat tag lists to nested, multi-level classification schemas.

Every delivery includes data-level and task-level quality metrics, plus a full audit trail suppourted by lineage report.

Labeled audio data flows directly into Version for lineage tracking and Observe for production drift monitoring no separate export intervention.

Get Data Infrastructure to Empower your AI